
Multiple horizons predictive modeling#
Environment setup#
We need to install some extra dependencies for this notebook if needed (when running jupyterlite).
%pip install -q skrub altair holidays plotly nbformat polars
Note: you may need to restart the kernel to use updated packages.
import datetime
import re
import warnings
from pathlib import Path

import altair
import cloudpickle
import numpy as np
import polars as pl
import pyarrow  # noqa: F401
import skrub
import tzdata  # noqa: F401
from sklearn.ensemble import HistGradientBoostingRegressor

from feature_engineering_lib import (
    feature_engineering_outputs,
    fetch_demand_history,
)
from single_horizon_prediction_lib import (
    TimeSeriesSplitter,
    get_cv_results,
    get_regressor,
)
from tutorial_helpers import plot_multi_horizon_prediction, plot_predictions

# Ignore warnings from pkg_resources triggered by Python 3.13's multiprocessing.
warnings.filterwarnings("ignore", category=UserWarning, module="pkg_resources")
Predicting multiple horizons with a grid of single output models#
We now have a pipeline that makes predictions for 1 horizon. To predict
multiple horizons, we just need to make one prediction for each horizon and
group them in a single dataframe. This follows the strategy of
Direct multi-step forecasting
where an independent model is trained for each horizon.

def concat_horizons(predictions):
    """
    Consolidate predictions of models for different horizons in one dataframe.
    """
    return pl.DataFrame({f"{h}h": v for h, v in predictions.items()})


def make_multi_horizon_pred(features, y, max_iter=100):
    """
    Create a full DataOp for predicting the specified horizons.

    increase max_iter for better predictions
    """
    regressor = get_regressor(max_iter=max_iter)
    predictions = {
        h: feat.skb.drop(["prediction_time", "target_time"])
        .skb.apply(regressor, y=y[f"{h}h"])
        .skb.set_name(f"pred_{h}h")
        for h, feat in features.items()
    }
    return skrub.deferred(concat_horizons)(predictions)
We inspect the pipeline on an example with only 3 horizons so that it is fast and reasonably easy to visualize. Later we will cross-validate a pipeline for all horizons between 1 and 25 hours.
TIME_HORIZONS = (1, 12, 24)
features, y = feature_engineering_outputs(TIME_HORIZONS, cv_splitter=TimeSeriesSplitter())

pred = make_multi_horizon_pred(features, y)
pred
Show/Hide graph
| 1h | 12h | 24h |
|---|---|---|
| 5.85e+04 | 6.42e+04 | 5.70e+04 |
| 5.74e+04 | 6.08e+04 | 5.67e+04 |
| 5.65e+04 | 5.88e+04 | 5.54e+04 |
| 6.06e+04 | 5.73e+04 | 5.55e+04 |
| 6.55e+04 | 5.73e+04 | 5.78e+04 |
| 4.35e+04 | 4.00e+04 | 4.09e+04 |
| 4.01e+04 | 4.06e+04 | 4.06e+04 |
| 3.77e+04 | 4.21e+04 | 3.91e+04 |
| 3.53e+04 | 4.16e+04 | 3.67e+04 |
| 3.35e+04 | 4.03e+04 | 3.39e+04 |
1h
Float64- Null values
- 0 (0.0%)
- Unique values
-
36,604 (100.0%)
This column has a high cardinality (> 40).
- Mean ± Std
- 4.98e+04 ± 1.04e+04
- Median ± IQR
- 4.80e+04 ± 1.41e+04
- Min | Max
- 2.93e+04 | 8.45e+04
12h
Float64- Null values
- 0 (0.0%)
- Unique values
-
36,546 (99.8%)
This column has a high cardinality (> 40).
- Mean ± Std
- 4.98e+04 ± 1.04e+04
- Median ± IQR
- 4.81e+04 ± 1.40e+04
- Min | Max
- 2.96e+04 | 8.41e+04
24h
Float64- Null values
- 0 (0.0%)
- Unique values
-
36,519 (99.7%)
This column has a high cardinality (> 40).
- Mean ± Std
- 4.98e+04 ± 1.04e+04
- Median ± IQR
- 4.81e+04 ± 1.40e+04
- Min | Max
- 2.95e+04 | 8.42e+04
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
| Column | Column name | dtype | Is sorted | Null values | Unique values | Mean | Std | Min | Median | Max |
|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 1h | Float64 | False | 0 (0.0%) | 36604 (100.0%) | 4.98e+04 | 1.04e+04 | 2.93e+04 | 4.80e+04 | 8.45e+04 |
| 1 | 12h | Float64 | False | 0 (0.0%) | 36546 (99.8%) | 4.98e+04 | 1.04e+04 | 2.96e+04 | 4.81e+04 | 8.41e+04 |
| 2 | 24h | Float64 | False | 0 (0.0%) | 36519 (99.7%) | 4.98e+04 | 1.04e+04 | 2.95e+04 | 4.81e+04 | 8.42e+04 |
No columns match the selected filter: . You can change the column filter in the dropdown menu above.
Please enable javascript
The skrub table reports need javascript to display correctly. If you are displaying a report in a Jupyter notebook and you see this message, you may need to re-execute the cell or to trust the notebook (button on the top right or "File > Trust notebook").
We want to define a scorer that will produce the Mean Absolute Percentage Error (MAPE) for each of the horizons, and also averaged across horizons.
from sklearn.metrics import mean_absolute_percentage_error


def neg_mape(y_true, y_pred):
    average = mean_absolute_percentage_error(y_true, y_pred)
    detail = mean_absolute_percentage_error(y_true, y_pred, multioutput="raw_values")
    return {"neg_mape_average": -average} | {
        f"neg_mape_{c}": -float(s) for c, s in zip(y_true.columns, detail)
    }


def neg_mape_scorer(estimator, X, y):
    return neg_mape(y, estimator.predict(X))


# We set this as the default scorer on our pipeline.
pred = make_multi_horizon_pred(features, y).skb.with_scoring(neg_mape_scorer)
Now we make the predictions and plot them. We notice that the 1h horizon qualitatively seems to stick better to the ground truth, which is expected and also corresponds to what we see in the MAPE.
cv_predictions, cv_scores = get_cv_results(pred)
split 0: 2023-06-01T00:00:00+00:00
{'neg_mape_average': -0.02232947721403171, 'neg_mape_1h': -0.015440365075048184, 'neg_mape_12h': -0.024987488108800453, 'neg_mape_24h': -0.026560578458246494}
split 1: 2023-09-01T00:00:00+00:00
{'neg_mape_average': -0.01796381480880521, 'neg_mape_1h': -0.014407342133597296, 'neg_mape_12h': -0.019401125792998335, 'neg_mape_24h': -0.02008297649981999}
split 2: 2023-12-01T00:00:00+00:00
{'neg_mape_average': -0.020414882263740827, 'neg_mape_1h': -0.013409988808983838, 'neg_mape_12h': -0.023323193362030658, 'neg_mape_24h': -0.024511464620207986}
split 3: 2024-03-01T00:00:00+00:00
{'neg_mape_average': -0.021697613888248025, 'neg_mape_1h': -0.013479675739038492, 'neg_mape_12h': -0.025605063404381866, 'neg_mape_24h': -0.02600810252132372}
split 4: 2024-06-01T00:00:00+00:00
{'neg_mape_average': -0.014447659175339078, 'neg_mape_1h': -0.009608652355501084, 'neg_mape_12h': -0.016501774032383017, 'neg_mape_24h': -0.017232551138133136}
split 5: 2024-09-01T00:00:00+00:00
{'neg_mape_average': -0.015690162810199255, 'neg_mape_1h': -0.00996556386802288, 'neg_mape_12h': -0.018241312571278093, 'neg_mape_24h': -0.018863611991296794}
split 6: 2024-12-01T00:00:00+00:00
{'neg_mape_average': -0.01865084868478969, 'neg_mape_1h': -0.010700630783230913, 'neg_mape_12h': -0.022927633453652233, 'neg_mape_24h': -0.022324281817485928}
split 7: 2025-03-01T00:00:00+00:00
{'neg_mape_average': -0.018246769832573697, 'neg_mape_1h': -0.010609025296709769, 'neg_mape_12h': -0.02190159037159969, 'neg_mape_24h': -0.02222969382941164}
plot_predictions(cv_predictions, horizon=12)
Evaluating and plotting the 24-horizon pipeline#
features_24_horizons, y_24_horizons = feature_engineering_outputs(
    range(1, 25), TimeSeriesSplitter()
)
pred_24_horizons = make_multi_horizon_pred(features_24_horizons, y_24_horizons).skb.with_scoring(
    neg_mape_scorer
)
We can plot the prediction for the first 24 hours past the end of our data
It is always good that our pipeline can make a prediction on some truly left-out data, as a sanity check which could find bugs in the way we set it up or did the cross-validation.
history = fetch_demand_history()
history_dates = history["time"]
new_date = ((history_dates - datetime.timedelta(seconds=1)).dt.truncate("1h")).max()
new_date
datetime.datetime(2025, 6, 27, 14, 0, tzinfo=zoneinfo.ZoneInfo(key='UTC'))
learner = pred_24_horizons.skb.make_learner(fitted=True)
prediction = learner.predict({"start": new_date, "end": None})
prediction
| 1h | 2h | 3h | 4h | 5h | 6h | 7h | 8h | 9h | 10h | 11h | 12h | 13h | 14h | 15h | 16h | 17h | 18h | 19h | 20h | 21h | 22h | 23h | 24h |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 | f64 |
| 48706.363604 | 49535.346149 | 48737.308255 | 46634.077723 | 45478.372548 | 46419.174392 | 45405.625278 | 42554.135427 | 40241.325018 | 38230.140695 | 36601.679075 | 34855.301869 | 35211.123479 | 36765.939274 | 37036.914405 | 38785.69964 | 41996.716134 | 44756.48305 | 46290.033723 | 47058.072669 | 46642.926287 | 46122.704669 | 44518.883723 | 45464.763092 |
plot_multi_horizon_prediction(history, new_date, prediction)
Finally, we run the cross-validation for all 24 horizons
cv_scores = pred_24_horizons.skb.cross_validate(verbose=2)
cv_scores
[CV] END .................................................... total time= 18.5s
[CV] END .................................................... total time= 18.9s
[CV] END .................................................... total time= 19.3s
[CV] END .................................................... total time= 19.9s
[CV] END .................................................... total time= 20.4s
[CV] END .................................................... total time= 20.8s
[CV] END .................................................... total time= 21.4s
[CV] END .................................................... total time= 21.7s
[Parallel(n_jobs=1)]: Done 8 out of 8 | elapsed: 2.7min finished
| fit_time | score_time | test_neg_mape_average | test_neg_mape_1h | test_neg_mape_2h | test_neg_mape_3h | test_neg_mape_4h | test_neg_mape_5h | test_neg_mape_6h | test_neg_mape_7h | ... | test_neg_mape_15h | test_neg_mape_16h | test_neg_mape_17h | test_neg_mape_18h | test_neg_mape_19h | test_neg_mape_20h | test_neg_mape_21h | test_neg_mape_22h | test_neg_mape_23h | test_neg_mape_24h | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 14.477851 | 3.992736 | -0.025187 | -0.015546 | -0.021700 | -0.023234 | -0.024381 | -0.025003 | -0.025612 | -0.024871 | ... | -0.026026 | -0.026412 | -0.025545 | -0.026407 | -0.026315 | -0.025282 | -0.026582 | -0.025905 | -0.026400 | -0.025551 |
| 1 | 14.864337 | 4.015449 | -0.019414 | -0.014513 | -0.018379 | -0.017870 | -0.018098 | -0.018770 | -0.019466 | -0.019107 | ... | -0.020227 | -0.020020 | -0.020597 | -0.020217 | -0.019833 | -0.020211 | -0.020187 | -0.020998 | -0.020236 | -0.019778 |
| 2 | 15.376853 | 3.902646 | -0.022472 | -0.013802 | -0.019232 | -0.020463 | -0.021634 | -0.022089 | -0.022794 | -0.023416 | ... | -0.023655 | -0.023630 | -0.023758 | -0.023420 | -0.023676 | -0.022783 | -0.023376 | -0.023256 | -0.023301 | -0.023644 |
| 3 | 15.945140 | 3.993246 | -0.024791 | -0.013649 | -0.020536 | -0.023158 | -0.024275 | -0.025264 | -0.024907 | -0.025155 | ... | -0.025459 | -0.025998 | -0.025721 | -0.026511 | -0.025880 | -0.025984 | -0.025514 | -0.025813 | -0.025738 | -0.025460 |
| 4 | 16.387096 | 4.007896 | -0.016321 | -0.009600 | -0.013465 | -0.015483 | -0.015621 | -0.016388 | -0.016306 | -0.015884 | ... | -0.016762 | -0.016890 | -0.017246 | -0.017464 | -0.017129 | -0.017115 | -0.017619 | -0.017540 | -0.018091 | -0.017257 |
| 5 | 16.864552 | 3.977739 | -0.017713 | -0.010154 | -0.015156 | -0.016742 | -0.017583 | -0.017792 | -0.018254 | -0.017975 | ... | -0.018325 | -0.018268 | -0.018424 | -0.018429 | -0.018263 | -0.017901 | -0.018276 | -0.018650 | -0.018693 | -0.018534 |
| 6 | 17.416836 | 3.941524 | -0.021238 | -0.010569 | -0.018032 | -0.019849 | -0.020624 | -0.021594 | -0.021833 | -0.022158 | ... | -0.021886 | -0.021707 | -0.022052 | -0.022042 | -0.021571 | -0.021844 | -0.021714 | -0.021762 | -0.021704 | -0.021948 |
| 7 | 17.850684 | 3.896491 | -0.021228 | -0.010578 | -0.017491 | -0.019699 | -0.021529 | -0.021379 | -0.021485 | -0.021368 | ... | -0.022457 | -0.022432 | -0.022284 | -0.022142 | -0.022725 | -0.022780 | -0.022193 | -0.022062 | -0.021966 | -0.022396 |
8 rows × 27 columns
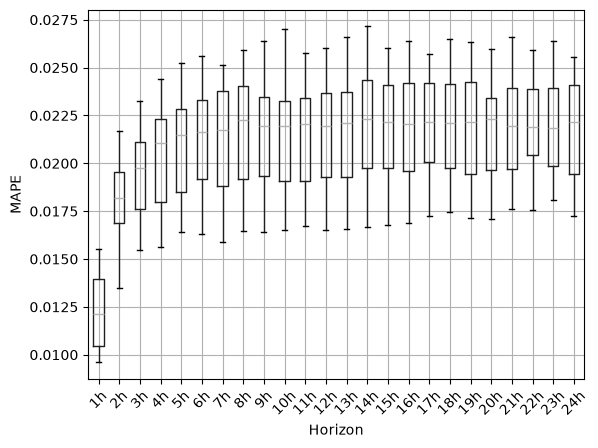
We can plot horizon vs MAPE to see if shorter horizons are easier to predict:
from matplotlib import pyplot as plt

(cv_scores.filter(regex="test_neg_mape_.*h") * -1).rename(
    columns=lambda c: c.removeprefix("test_neg_mape_")
).boxplot()
plt.xticks(rotation=45)
plt.xlabel("Horizon")
plt.ylabel("MAPE")
Text(0, 0.5, 'MAPE')
Hyperparameter Tuning#
We load the dataop we dumped in the previous notebook and search for the best hyperparameters with optuna.
env = {"start": "2021-03-23", "end": "2025-05-31"}
We keep the last split of the default splitter as a held-out test set on which to validate the selected pipeline.
outer_split = pred.skb.train_test_split(env)
outer_split["X_test"]
| prediction_time |
|---|
| datetime[μs, UTC] |
| 2025-03-01 00:00:00 UTC |
| 2025-03-01 01:00:00 UTC |
| 2025-03-01 02:00:00 UTC |
| 2025-03-01 03:00:00 UTC |
| 2025-03-01 04:00:00 UTC |
| … |
| 2025-05-30 20:00:00 UTC |
| 2025-05-30 21:00:00 UTC |
| 2025-05-30 22:00:00 UTC |
| 2025-05-30 23:00:00 UTC |
| 2025-05-31 00:00:00 UTC |
We use persistent storage for our optuna database so we can resume or inspect it after the current process exits.
%pip install -q optuna
# import optuna
# print(f"optuna version: {optuna.__version__}")
Note: you may need to restart the kernel to use updated packages.
To keep the notebook fast we reload an existing search that has 100 iterations (specified by storage and study_name), and resume it to add 2 more iterations.
search = pred.skb.make_randomized_search(
    backend="optuna",
    storage="sqlite:///multiple_horizons_prediction.optuna",
    study_name="randomized_search",
    n_iter=2,
    n_jobs=1,
    refit="neg_mape_average",
)

search.fit(outer_split["train"])
search.score(outer_split["test"])
Running optuna search for study randomized_search in storage sqlite:///multiple_horizons_prediction.optuna
[I 2026-11-09 15:44:53,359] Using an existing study with name 'randomized_search' instead of creating a new one.
[I 2026-11-09 15:45:18,893] Trial 128 finished with value: -0.01808702404677204 and parameters: {'0:temperature_only': '0:True', '1:cities': "0:'all'", '2:learning_rate': 0.15828511506161932, '3:loss': "1:'poisson'", '4:max_leaf_nodes': 107, '5:min_samples_leaf': 81}. Best is trial 128 with value: -0.01808702404677204.
[I 2026-11-09 15:45:44,611] Trial 129 finished with value: -0.017967446108011393 and parameters: {'0:temperature_only': '0:True', '1:cities': "0:'all'", '2:learning_rate': 0.15689680099633974, '3:loss': "1:'poisson'", '4:max_leaf_nodes': 108, '5:min_samples_leaf': 78}. Best is trial 129 with value: -0.017967446108011393.
[I 2026-11-09 15:45:44,628] Using an existing study with name 'randomized_search' instead of creating a new one.
{'neg_mape_average': -0.01753761292338198,
 'neg_mape_1h': -0.009781390524764856,
 'neg_mape_12h': -0.021046797521276507,
 'neg_mape_24h': -0.02178465072410458}
search.plot_results()